AI & Machine Learning · Open-source build
Document understanding pipeline
PDFs, scans and spreadsheets turned into structured, validated records with a human review queue for what the model is unsure about.
What it is
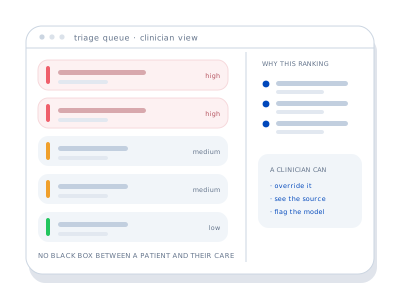
Docling parses layout, tables and reading order from documents. A model extracts fields against a schema, with confidence per field. Records above the threshold flow straight through; the rest land in a review interface where a person confirms or corrects, and every correction becomes training data.
What the build consists of
- 01Layout-aware parsing of PDFs and scans, tables preserved as tables
- 02Schema-driven extraction with per-field confidence
- 03Validation rules: totals must add up, dates must be plausible
- 04Review queue with keyboard-first correction and audit trail
- 05Corrections fed back into the evaluation set
- 06Throughput and accuracy dashboards by document type
What you see in a demo
A stack of invoices in three layouts becoming one clean table, with the two ambiguous ones waiting in the queue instead of silently wrong.